Google Unveils AI Video Co-Director for Long-Form Stories
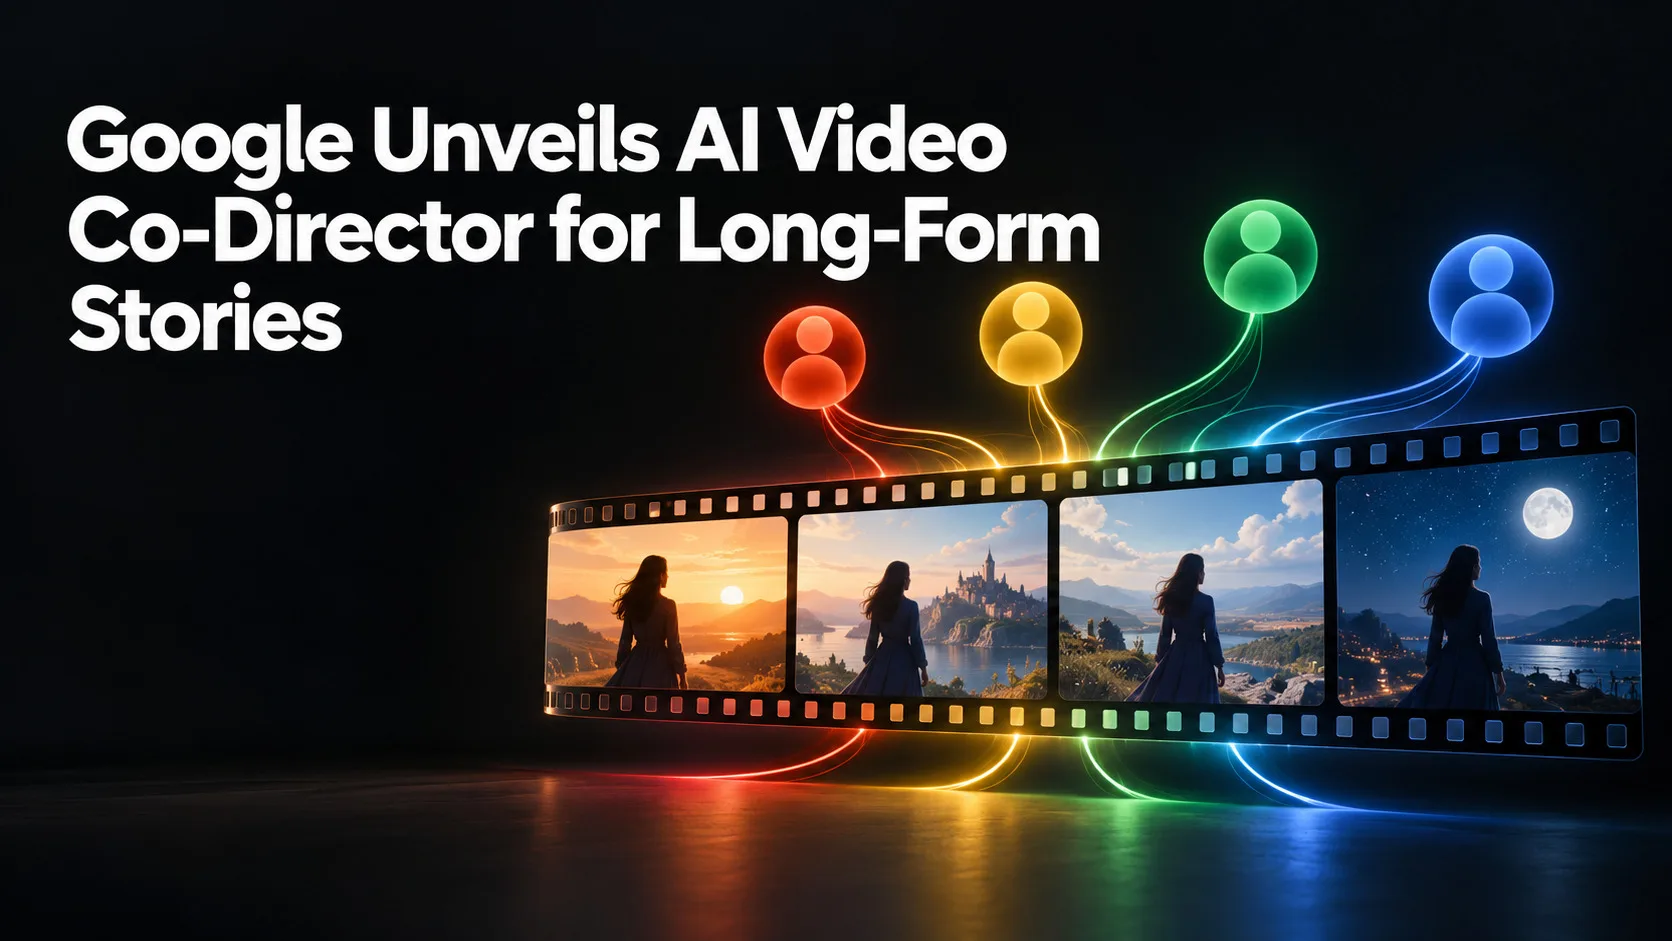
Google unveils AI video co-director research designed to make long-form generated video more coherent by coordinating planning, production, memory and quality-control agents. Google says the framework can produce minutes-long narratives while reducing the character drift and cascading errors that often emerge when short AI-generated clips are chained together.
The September 24 disclosure combines four research systems built around Gemini and Veo. It frames video creation as a global optimization problem, with specialized agents repeatedly planning, generating, judging and revising a production instead of relying on one linear sequence of prompts.
The research package addresses four production bottlenecks:
- Co-Director selects an overall creative strategy.
- CANVAS preserves characters, locations and props.
- A²RD builds video segment by segment.
- VQQA detects defects and refines prompts.
Google Unveils AI Video Co-Director Research Suite
Modern diffusion models can create polished clips, but longer narratives demand more than isolated visual quality. Clothing can change between shots, rooms can acquire different geometry and a mistake in an early asset can contaminate every later scene that depends on it.
Google’s approach adds an orchestration layer above the underlying generation models. It separates creative synthesis from consistency enforcement, giving different agents responsibility for the storyline, visual anchors, motion, sound and review while a shared process maintains the production’s intended direction.
The company describes the architecture as model-agnostic, although its demonstrations use Gemini and Veo. That distinction matters: the research concerns the workflow that organizes generation rather than a newly released foundation model or a consumer video-editing product.
Google also says outputs inherit safeguards available in the underlying models, including SynthID watermarking. It proposes additional classifiers for completed videos because individually safe clips can still create problematic meaning when assembled into a longer sequence.
How Co-Director Plans Each Production
Co-Director begins with an orchestrator that uses a multi-armed bandit algorithm to explore combinations of creative strategy, narrative mode and visual style. The selected configuration becomes a top-down brief for the agents that handle pre-production and production.
A pre-production agent converts the brief and source assets into a storyline and storyboard. Production agents then create keyframes, video segments, voiceover and music. A multimodal model judges the assembled cut and returns separate scores to guide another optimization round.
This feedback loop is designed to make a failure traceable and correctable. In a conventional prompt chain, a poor early choice can be difficult to identify after several modules have transformed it. Co-Director instead evaluates the finished result against the original creative dimensions and adjusts the strategy across repeated runs.
The accompanying paper evaluates the approach with GenAD-Bench, a dataset covering 400 fictional advertising scenarios. Google reports a peak quality score of 81.4, while the researchers say the framework also improved story consistency on a separate narrative benchmark.
Further Reading
CANVAS and A²RD Track Long-Range Continuity
CANVAS tackles visual continuity before full video synthesis. Its persistent memory stores representations of characters, locations and objects, allowing the storyboard agents to retrieve established visual anchors when a narrative returns to an earlier scene after several intervening shots.
The CANVAS paper reports gains over its strongest baseline of 21.6% for background continuity, 9.6% for character consistency and 7.6% for props. Those measures target a familiar weakness of generative video: an attractive single frame does not guarantee that the next frame or later scene preserves the same fictional world.
A²RD extends continuity into minutes-long output. Its retrieve-synthesize-refine-update cycle generates one segment at a time while consulting multimodal memory. The agent can extrapolate to advance the narrative or interpolate when it needs to anchor a segment to established people and environments.
Researchers tested A²RD on videos lasting from one to ten minutes. Its paper reports improvements of up to 30% in consistency and 20% in narrative coherence over existing baselines, with human evaluations also favoring its motion and transitions.
VQQA Turns Visual Critiques Into Prompt Revisions
VQQA provides the quality-control layer. It creates questions tailored to the user’s request, asks a vision-language model to evaluate the generated video and converts that critique into natural-language guidance for a revised prompt. The generator then samples a new candidate rather than editing individual pixels.
A global selector compares every candidate from the refinement path against the original request. That step is intended to prevent a local correction from solving one defect while pushing the overall video away from the user’s broader intent.
The VQQA paper reports absolute improvements of 11.57% on T2V-CompBench and 8.43% on VBench2 over unoptimized generation. The system works through a black-box interface, so it does not require access to the video model’s internal weights.
The research remains a collection of frameworks and papers rather than a public end-to-end filmmaking service. Its significance is architectural: Google is treating long-form video as a coordinated production system, where memory, evaluation and iterative planning can matter as much as the raw capability of the generator.